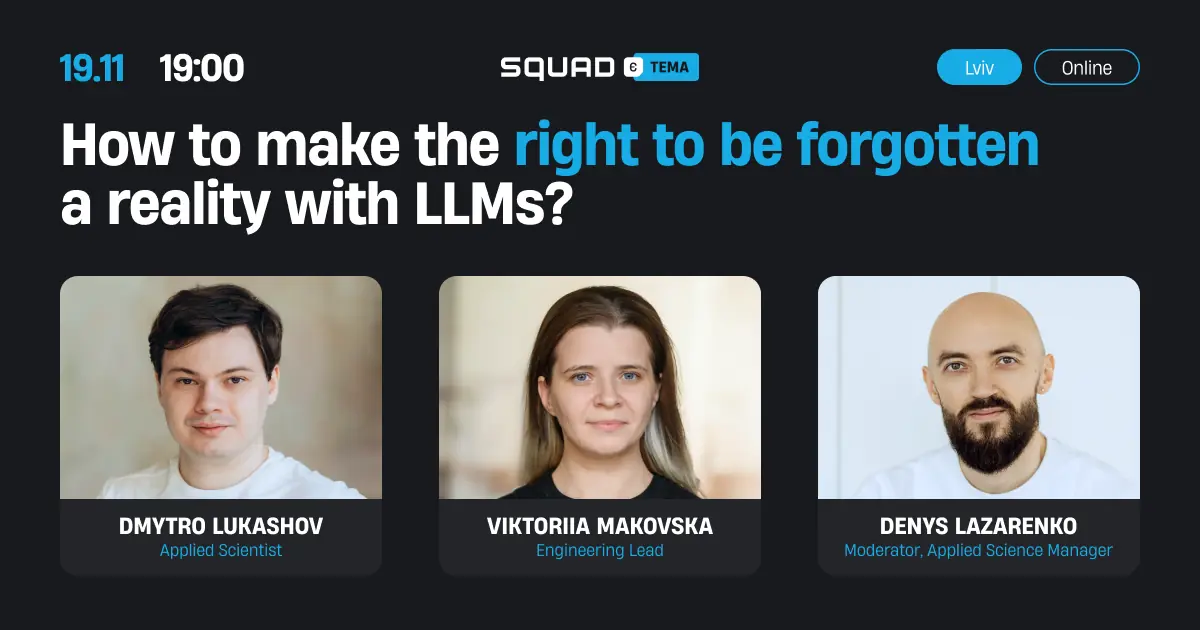
A meetup for those who research, fine-tune, or deploy LLMs: how to distinguish genuine forgetting from merely hiding information, how to verify the results, and when unlearning is worth applying despite its limitations.
Large language models can memorize and reproduce personal data, confidential information, and fragments of copyrighted content. Simply removing documents from the training dataset does not solve this problem, while retraining a model from scratch can be costly and impractical.
On November 19 in Lviv, SQUAD’s AI specialists will explore how LLM unlearning aims to address this challenge — and why implementing the “right to be forgotten” in language models is more complicated than it may seem.
Join us for insightful discussions and engaging networking!
Registration is required.
A meetup for those who research, fine-tune, or deploy LLMs: how to distinguish genuine forgetting from merely hiding information, how to verify the results, and when unlearning is worth applying despite its limitations. Large language models can memorize and reproduce personal data, confidential information, and fragments of copyrighted content. Simply removing documents from the training […]
https://itcluster.lviv.ua/wp-content/uploads/2026/11/squad_e-tema_1200x630_en.png


